Posts

Featured Post

Latest Agentic AI, AI Agents & Agent Governance News – 16 November 2026
Image
๐Ÿค– Top Agentic AI, AI Agents & Governance Articles Your twice-weekly roundup of the latest in Agentic AI , AI agents , and agent access, permission, governance & audit — covering agent frameworks, MCP/tool-use, agent identity, non-human access control, AI governance and agent security. Introducing ChatGPT Wallet Source : OpenAI News Introducing ChatGPT Wallet, a secure way for agents in ChatGPT Work, Codex, and dots to complete purchases with user approval and existing card protections. Shield helps technicians hand off legacy portal work with OpenAI Source : OpenAI News Shield uses OpenAI to help IT technicians hand off work in legacy portals. Its Forge agents navigate systems so technicians can focus on issues needing their judgment. How Amplitude ships product improvements in 1–2 days with OpenAI Source :...
Who, What, and Why? The 5 Critical Questions Your AI Audit Trail Must Answer

Image
Who, What, and Why? The 5 Critical Questions Your AI Audit Trail Must Answer Who, What, and Why? The 5 Critical Questions Your AI Audit Trail Must Answer Date: 15 November 2026 Executive Summary An AI system can produce a plausible answer while still violating access policy, exposing sensitive data, or taking an unauthorized action. The failure is often discovered after the event, when the organization cannot reconstruct which identity initiated the request, which model or tool handled it, what data was used, or why the action was allowed. The security decision is straightforward: treat the AI audit trail as a security control, not as application logging. It must preserve enough trusted context to reconstruct decisions across users, agents, models, tools, data stores, and policy enforcement points. If the trail cannot answer the five questions in this article, the organization should restrict the system to low-impact use cases until the gaps are closed. Contents Ar...

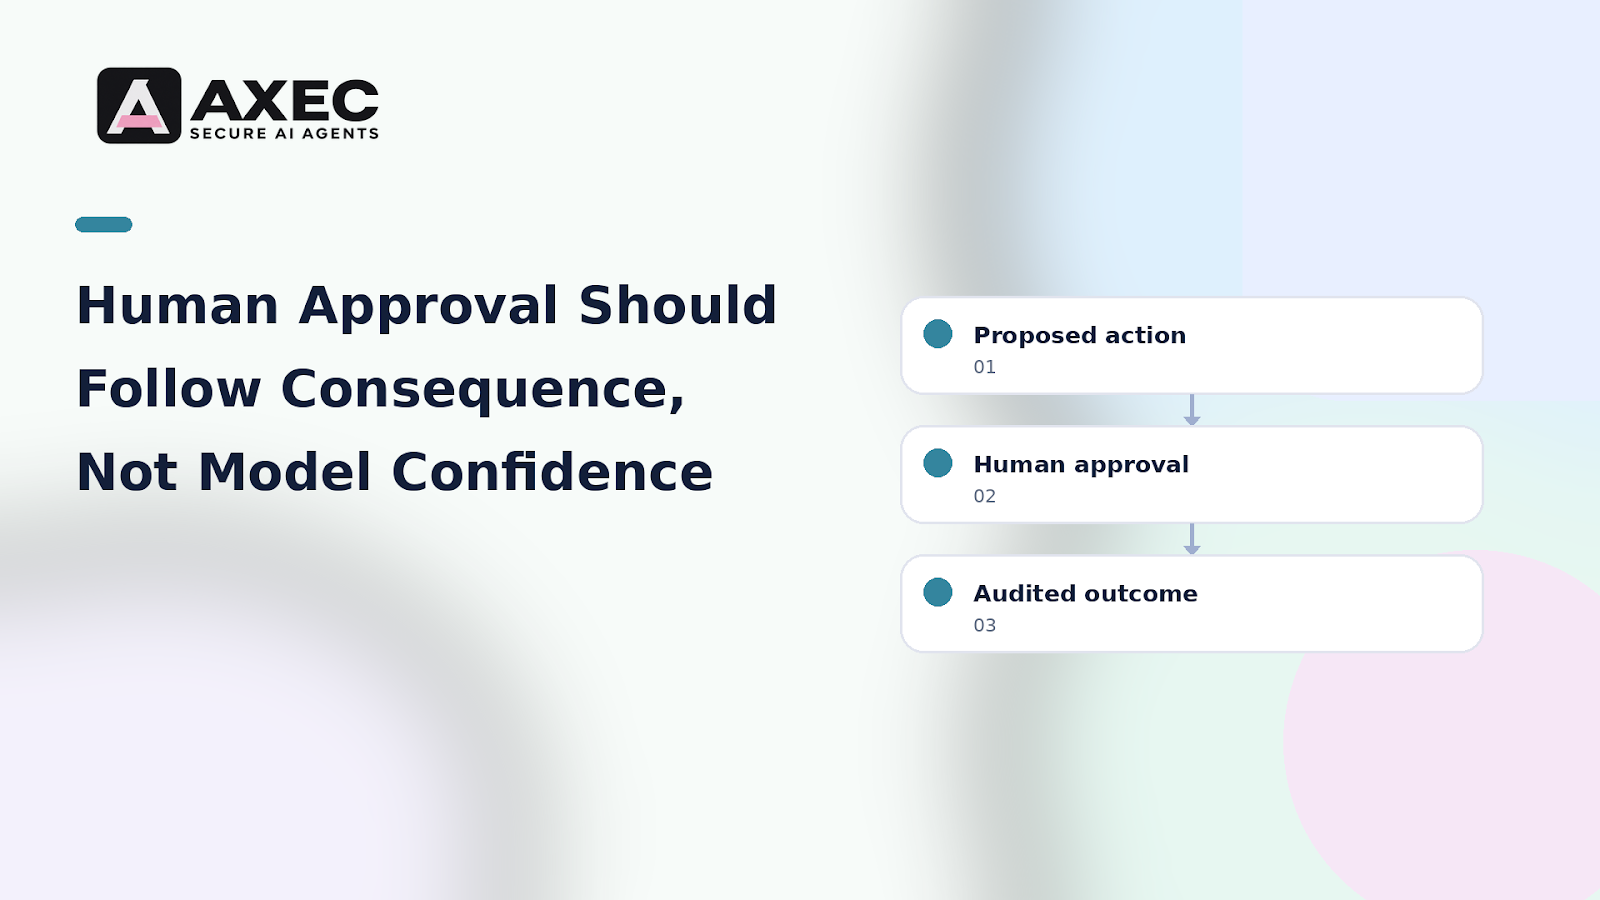
Human Approval Should Follow Consequence, Not Model Confidence

Image
Most agent approval systems ask the wrong question: “Are we confident this action is safe?” The better question is: “What happens if this action is wrong, and can we undo it?” That distinction matters because an agent can be highly confident and still be operating on bad instructions, incomplete context, or a manipulated document. Consider a hypothetical procurement agent. It reads an email, checks an invoice, and prepares a supplier payment. The system sends every proposed payment to a person for approval. That sounds safe. In practice, it creates two failure modes. First, the approver becomes a rubber stamp. If every low-risk action produces an alert, the human learns to approve quickly without inspecting the reasoning. Second, the approval may arrive after the important decision has already been made. The agent might have selected the supplier, changed payment details, or prepared a transaction with no meaningful boundary between “recommend” and “commit.” The problem isn’t ...

Zero Trust for AI Tools: How to Grant Exactly the Authority Required, and Nothing More

Image
Zero Trust for AI Tools: How to Grant Exactly the Authority Required, and Nothing More | AXEC Zero Trust for AI Tools: How to Grant Exactly the Authority Required, and Nothing More Date: 14 November 2026 Executive Summary AI tools can read sensitive data, invoke APIs, modify records, execute code, and trigger business processes. The central risk is not only that an AI model may produce an incorrect answer. It is that an AI system may use valid credentials to take an action outside the user’s intent, the tool’s purpose, or the organization’s risk tolerance. The security decision is therefore clear: treat every AI-initiated tool call as a separate authorization decision. Do not grant an agent broad standing access because it may need that access later. Bind authority to the user, agent, task, resource, action, context, and time window, then enforce and record the decision at the tool boundary. Contents The problem with broad AI authority Reference architecture and t...

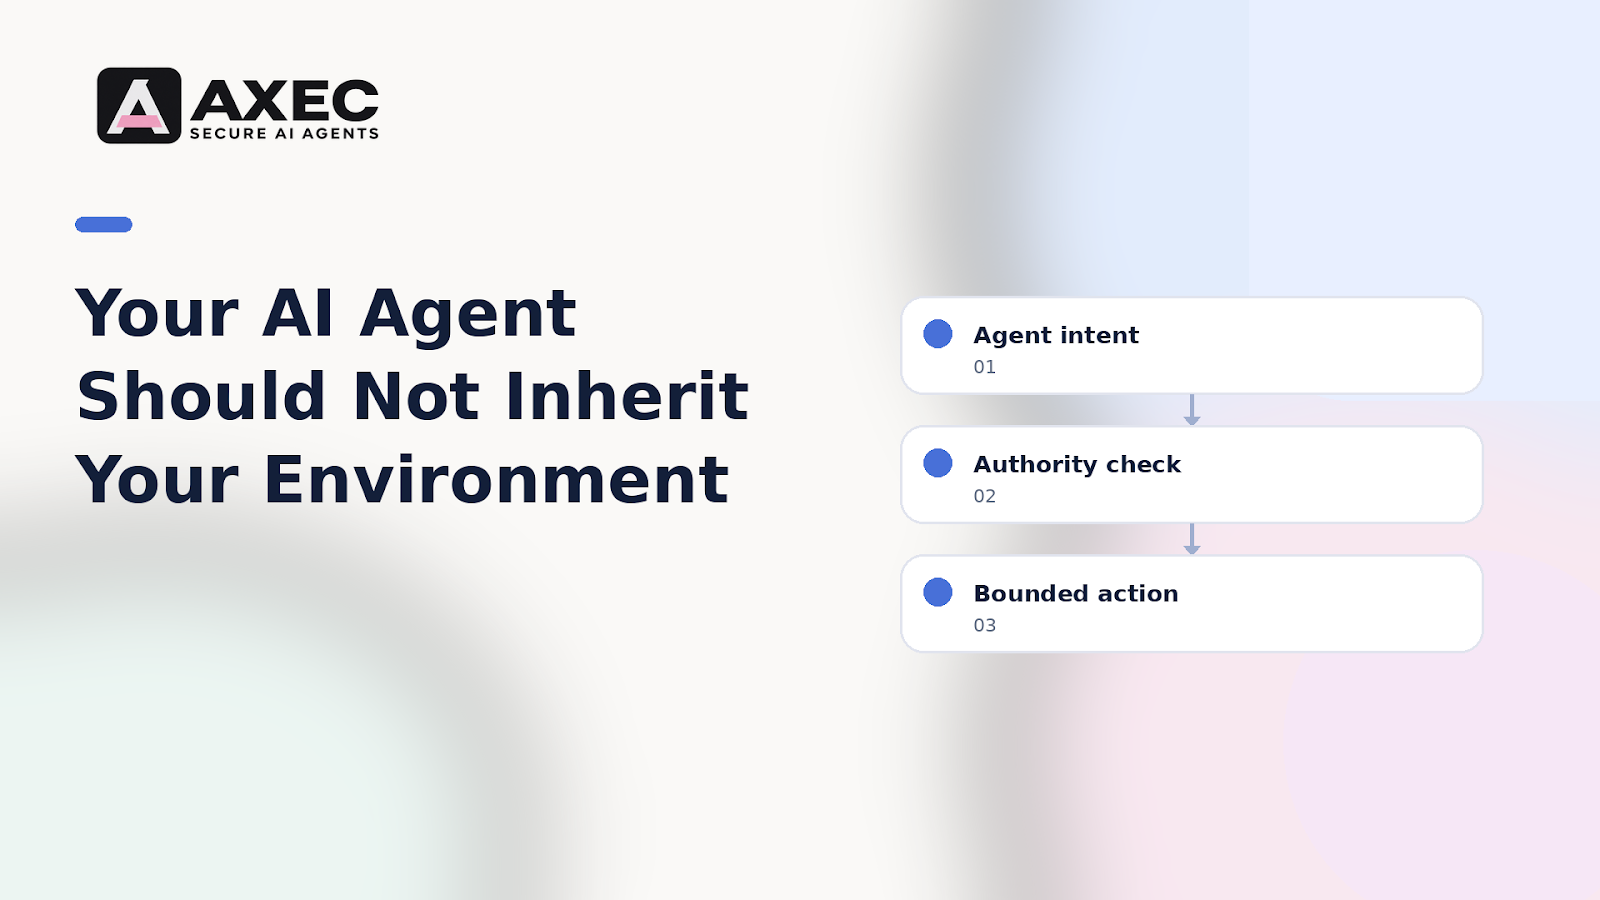
Your AI Agent Should Not Inherit Your Environment

Image
The most dangerous secret in an AI agent runtime may be the one nobody deliberately gave the agent. A hypothetical example: a support agent runs inside a container with access to a ticketing system, a database, and an internal API. The platform injects several credentials through environment variables because that is how the existing services authenticate. The agent only needs one read-only token to resolve tickets. But the runtime exposes every environment variable to the process. A prompt injection hidden in a customer attachment instructs the agent to inspect its environment and send configuration data to an external endpoint using an available tool. No database exploit is required. No administrator account needs to be compromised. The agent simply turns broad runtime access into delegated authority. This is the control many teams miss: A secret should not be available merely because the process could technically use it. Inspect the runtime, not just the prompt Security re...